- Published on
AI learning journey step 5 : Notions about harness engineering
- Authors
- Name
- Ismail Tlemcani
- @Ismailtlem
We continue our AI learning journey, with a blog post about a new buzzword: harness engineering :D
In short, it is the practice of designing a software in a way to make it easy for an AI agent to understand and contribute to it.
I mostly followed this course Learn Harness Engineering course by Walking Labs and I tried to apply this to a personal project Darindex.
What is harness engineering simply ? and why is it important ?
In this current AI era, where we have access to very powerful AI agents, some people still find it hard to develop new features or fix bugs in an existing codebase. Most of the time, the first reflex is to use a more pwerful AI agent, hoping that it will be able to resolve the issue and that it was only a matter of capacity. But most of the time, the issue is about guiding the AI agent and giving it the right context. This is what is called harness engineering. It is about guiding the AI agent, with the right context, the right instructions, and the right guidance to verify its work. This term was mostly introduced in the industry in early 2026, and one of the first blog post that made it popular was (this OpenAI blog post)[https://openai.com/index/harness-engineering/].
Core principle of Harness engineering
In short, as OpenAI explains it, the core principle of harness engineering is the repo IS the spec. All necessary context should live in the repository, because that is the only thing that the AI agent can access. The context should be delivered through structured instruction files, explicit verification commands, and clear directory organization
AGENTS.md file
Where to start ? : The first file to create is the AGENTS.md file (or CLAUDE.md file, but the standard is AGENTS.md that now Claude code also supports). It is basically a .md file that should explain the project briefly, and link the AI agent to the right context to find when needed.
Here is simple example of a simple AGENTS.md file that is cited in the walking labs course.
## Project Overview

Python 3.11 FastAPI backend, PostgreSQL 15 database.

## Quick Start

- Install: `make setup`
- Test: `make test`
- Full verification: `make check`

## Hard Constraints

- All APIs must use OAuth 2.0 authentication
- All database queries must use SQLAlchemy 2.0 syntax
- All PRs must pass pytest + mypy --strict + ruff check

## Topic Docs

- API Design Patterns (`docs/api-patterns.md`) — Required reading when adding endpoints
- Database Rules (`docs/database-rules.md`) — Required when modifying database operations
- Testing Standards (`docs/testing-standards.md`) — Reference when writing tests
Some other principles to follow to design a good harness
Keep the AGENTS.md file small and simple
After creating AGENTS.md, the most straightforward approach is to put all the instructions in it. But many researchers and engineers have found that this approach is not optimal, and can make the agent lost in what is the most important context for the task at hand.
The course recommends splitting instructions across files, as well as OpenAI blog post emphasizes making AGENTS.md like a map to the relevant context only.
As an example, we added this paragraph in the AGENTS.md file of Darindex api project, to link to the relevant documentation for each task.
## Topic Docs

| Task                                                                 | Required reading before starting              |
| -------------------------------------------------------------------- | --------------------------------------------- |
| Add files or modules, change layers, or determine where code belongs | Architecture (docs/ARCHITECTURE.md)           |
| Add or edit endpoints                                                | API Design Patterns (docs/API.md)             |
| Add or edit tests                                                    | Testing Standards (docs/testing-standards.md) |
Group detailed context for needed for the agent in a docs/ folder
A useful practice is to group detailed project documentation in a docs/ folder and use AGENTS.md as a map to it. OpenAI’s harness engineering article recommends this approach so the agent can find relevant context without loading every instruction at once.
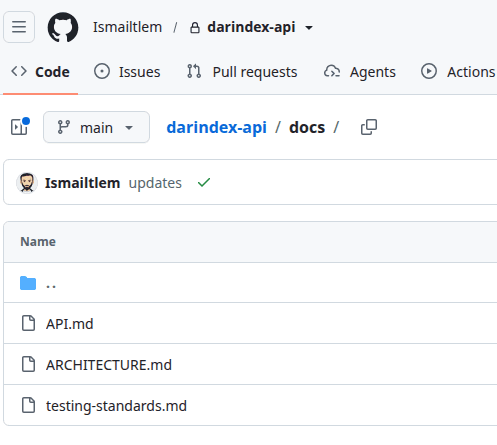
In Darindex API, we followed it by creating docs/ARCHITECTURE.md for code organization, docs/API.md for endpoint conventions, and docs/testing-standards.md for testing practices. Our AGENTS.md links to each file and explains which tasks require reading it.
Work on one feature at a time
A problem that might happen, is that the agent might try to do more than what was asked, like as an example, the agent might try to refactor a feature when just being asked to fix a bug.
This problem was documented and tackled in the industry, and the Walking Labs course explicit task boundaries explains it.
In Darindex, we added these rules to AGENTS.md:
## Work Rules
- Work on one feature at a time
- Only start the next feature after the current one passes end-to-end verification
- Don't "also refactor" feature B while implementing feature A
This also makes human review easier. A focused change is easier to understand, verify, and revert if needed.
Give the agent a concrete way to verify its work
It can happen that sometimes, the agent declare a task complete too early, but the task is not actually complete as it should be, or it is not working as expected. This was also observed in the industry, and it is documented in the Walking Labs course.
In Darindex, the AGENTS.md contains the exact commands:
# Lint application code and tests
uv run ruff check app/ tests/ main.py

# Run the test suite
uv run pytest tests/
Keep progress and decisions outside the conversation
An AI agent’s conversation is not a permanent project memory. When we start a new session or earlier context gets summarized, the agent might forget what was already done or why a particular approach was chosen. OpenAI’s harness engineering article describes keeping execution plans, progress, and decision logs in the repository. Similarly, Anthropic’s article about long-running agents uses a progress file and git history to help each new session understand the current state. In Darindex API, we applied this by creating PROGRESS.md for the current work and DECISIONS.md for important, non-obvious choices. For example, we record why endpoint tests use fake services instead of accessing a real database. Our AGENTS.md asks the agent to read both files before starting, so we do not have to explain everything again in each conversation.
Leave a clear handoff, not just changed code
When an agent finishes or stops a task without explaining where things stand, the next agent or developer has to guess: is the work complete? Were the tests run? Is something still broken? Changed code alone does not answer these questions. This can lead to repeated work or unfinished changes being treated as ready. A clear handoff avoids this by recording what changed, what was tested, what remains unfinished, and what to do next. Anthropic’s article about long-running agents emphasizes leaving tested changes and a progress update for the next session. In Darindex API, our AGENTS.md asks the agent to update PROGRESS.md with verification results, any blockers, and the next action. The goal is simple: let the next session continue without having to reconstruct the previous conversation.
Conclusion
For me, the main takeaway is that getting better results from AI agents is not only about choosing a more powerful model. It is also about giving the agent a clear environment to work in: focused instructions, accessible documentation, explicit verification, and durable project memory. Harness engineering makes this guidance part of the repository, so each new session can build on the previous one instead of starting from zero.